Pexo
Stable Video Diffusion

Stable Video Diffusion
Start with a still. Explore the motion.

Stable Video Diffusion is Stability AI’s image-to-video model family. The released SVD checkpoints use a single image to generate a short moving sequence, giving photographers, designers, and developers a way to explore motion around an existing composition.

SVD remains available for self-hosting. Stability AI’s hosted SVD API ended on July 24, 2025.

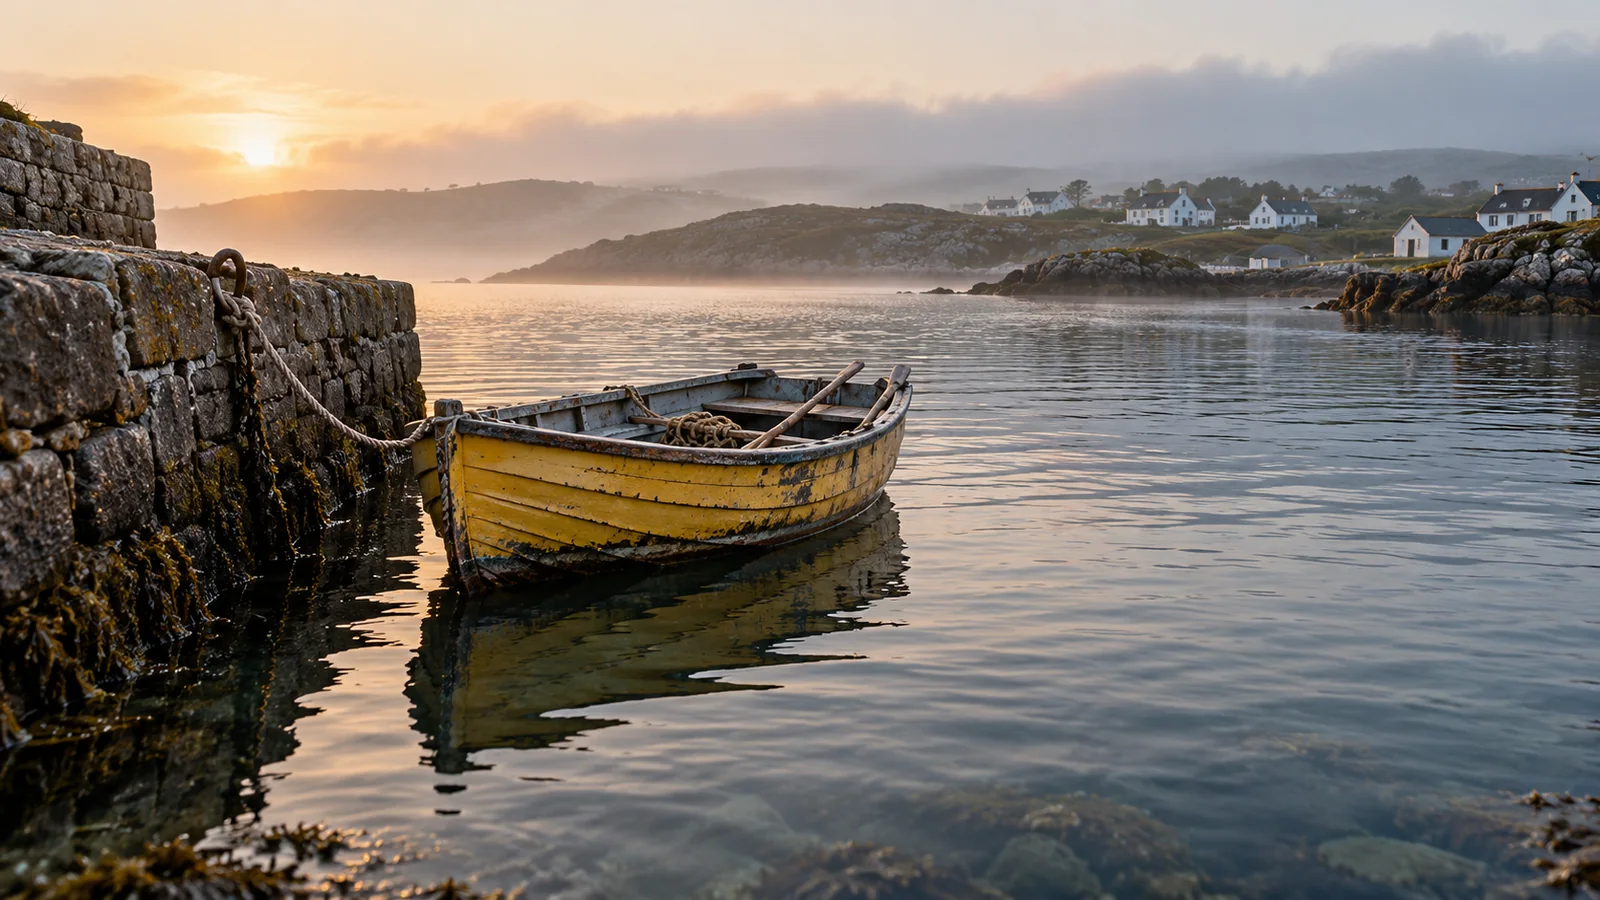
A weathered yellow fishing boat floating beside a stone harbor wall at dawn
Image → video

A still frame establishes the scene

14 or 25 frames

SVD and SVD-XT checkpoints

Self-hosted workflow

Weights and reference code available

Core capabilities

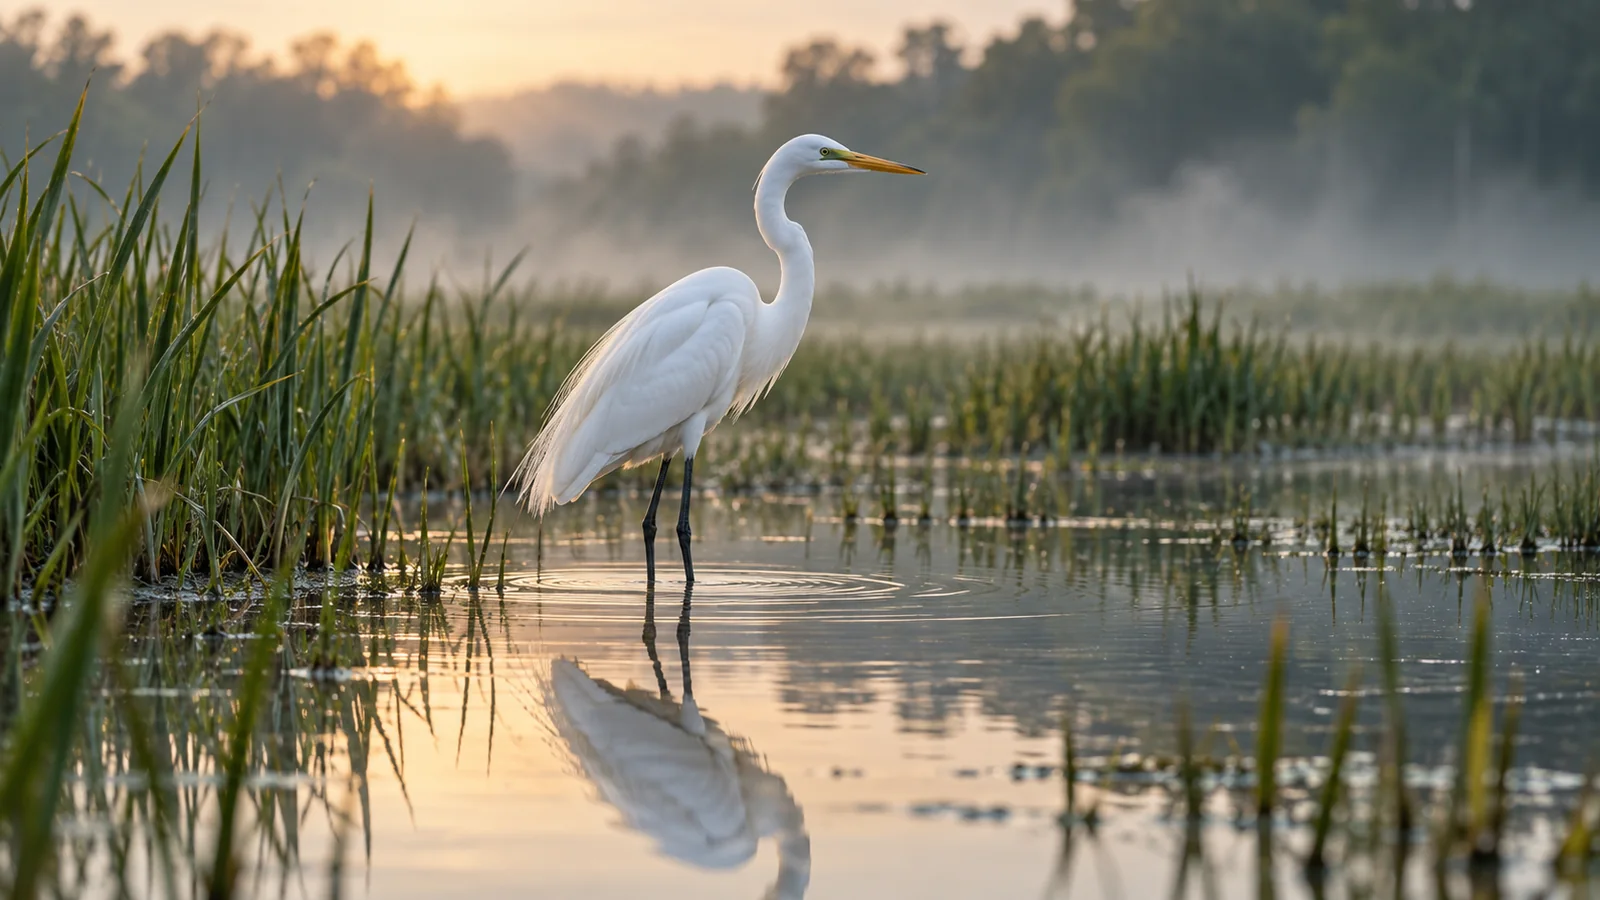
A white egret and its reflection in shallow marsh water among soft green reeds
Input image / motion goal

Keep the egret and reeds recognizable while exploring small changes in the water, reflections, and bird position.

01 / Begin with the composition

Image-conditioned video generation

Let the image define what belongs in the shot.

The source frame supplies the subject, materials, lighting, and setting. An egret in shallow marsh water offers a clear visual anchor, with ripples and reflections providing room for movement. Choose an image whose main subject remains easy to recognize when the frame begins to change. For a longer edit built from several stills, a photo slideshow can connect the selected images.

The original SVD and SVD-XT checkpoints take an image as conditioning; they do not accept text direction.
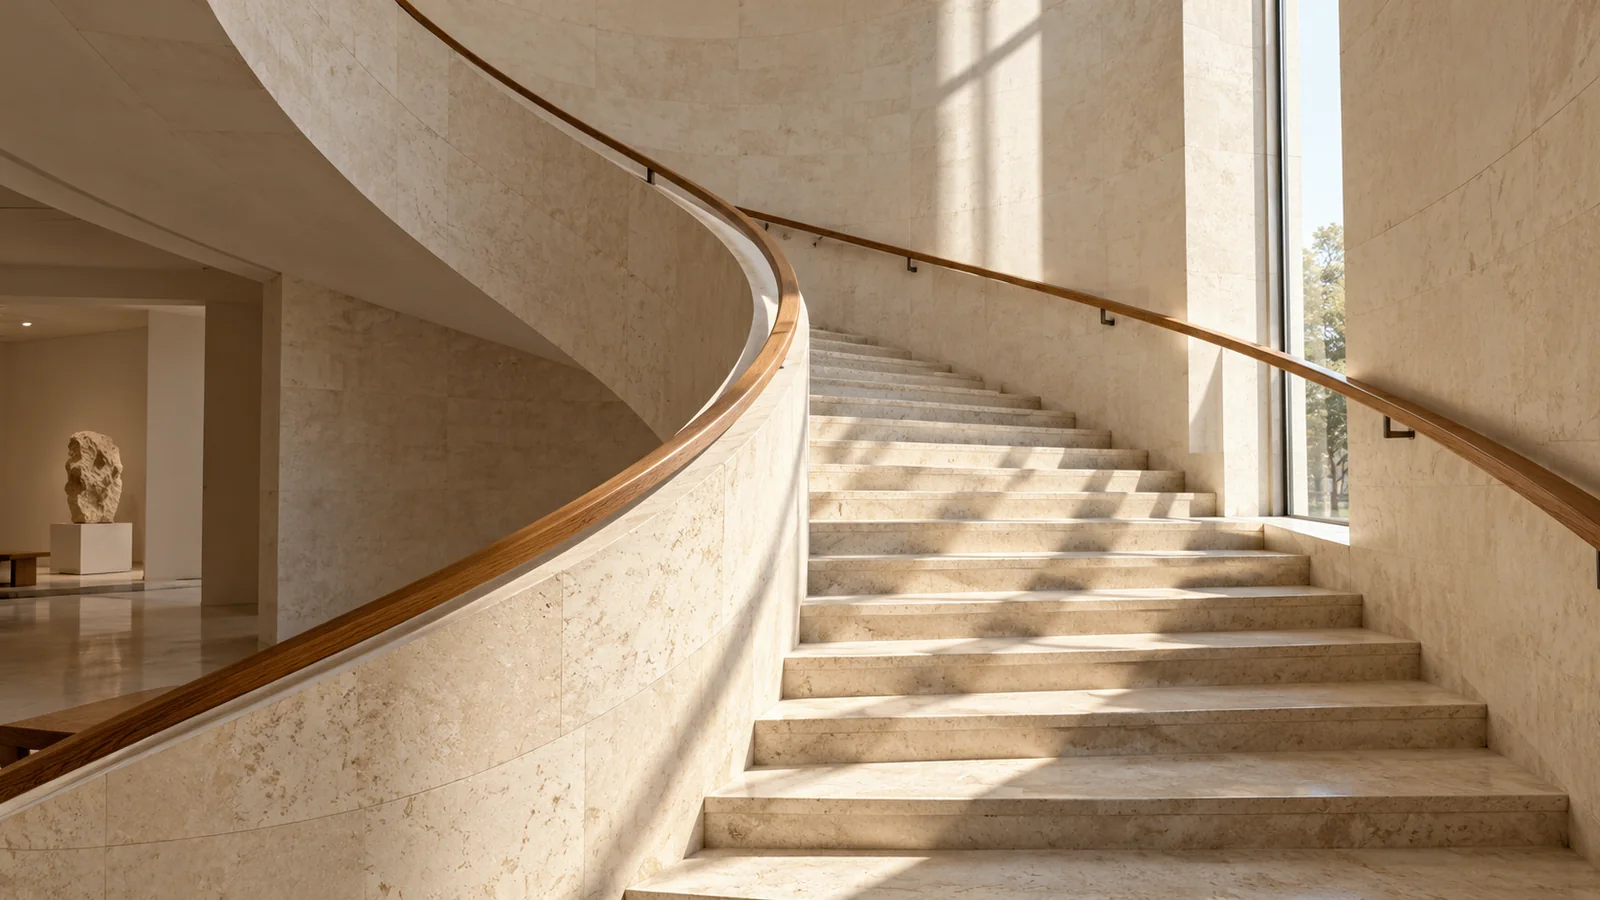
A curved limestone staircase with an oak handrail and long window shadows
Sampling review

Compare how the near handrail and distant steps shift. Favor a sample with readable depth and stable architectural lines.

02 / Movement and depth

Explore motion through sampling settings

Change one setting, then compare the sequence.

The reference sampler exposes frame-rate conditioning, a motion bucket, image-conditioning augmentation, and a random seed. These controls let you explore different samples from the same image. In an architectural scene, inspect the stair edges and handrail as carefully as the apparent camera movement.

A motion bucket adjusts motion conditioning. It is not a command for a specific pan, orbit, or camera path.

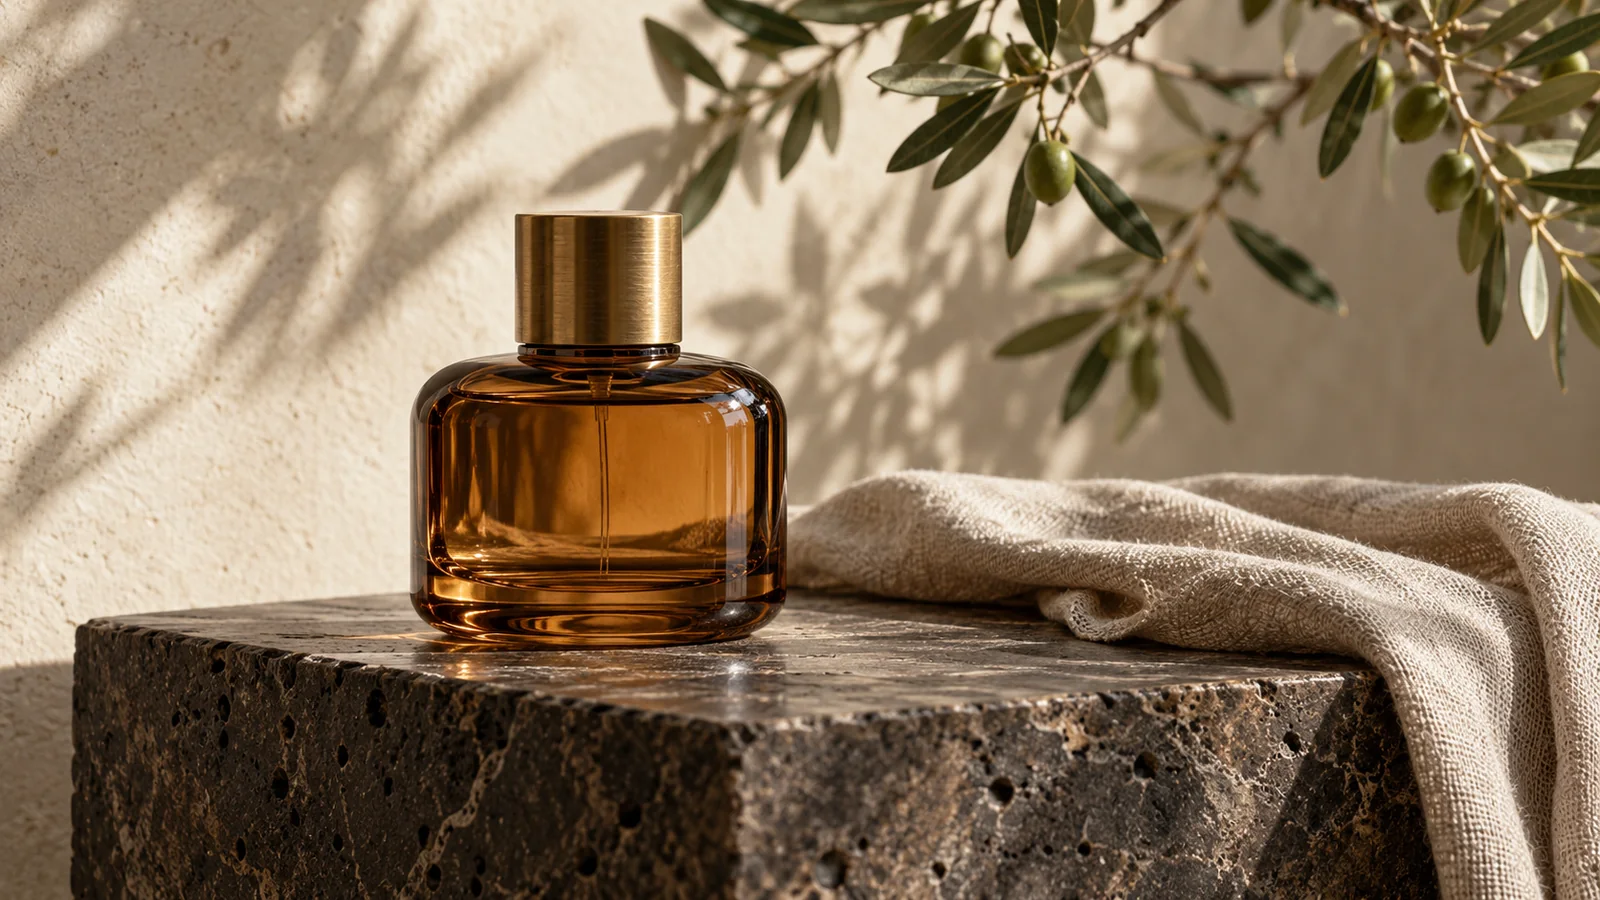
An unlabeled amber perfume bottle on a stone plinth with linen and olive-branch shadows
Product motion review

Follow the bottle silhouette, cap, and glass reflections across the frames. Keep the background movement subordinate to the product.

03 / SVD and SVD-XT

Choose the frame count for the moment

Give the movement enough frames to read.

SVD generates 14 frames; SVD-XT extends the sequence to 25. Both were trained at 1024 × 576 pixels. For a product composition, compare whether the longer sample gives reflections and background movement a useful progression while retaining the bottle’s shape. A product reveal video can build on the selected shot with a clear opening and close.

Frame count and playback speed work together: the same sequence plays for a different duration when exported at a different fps.

SVD checkpoint formats

The original checkpoints share the same image size and differ in generated frame count.

Input

One still image

The image establishes the visual content.

Image size

1024 × 576

Width × height for the released checkpoints.

Sequence

14 / 25 frames

SVD / SVD-XT respectively.

Timing

Configurable fps

Playback speed determines clip duration.

SVD vs SVD-XT

Choose between the original short sequence and its longer-frame variant.

DimensionSVDSVD-XT
Generated frames1425
Training image size1024 × 5761024 × 576
ConditioningSingle imageSingle image
Text-prompt controlNot supportedNot supported
RelationshipOriginal image-to-video checkpointFine-tuned from SVD for more frames
Practical choiceA shorter motion sampleMore frames for the movement to develop

Use cases

Explore Pexo Create workflows for image sequences, product stories, and visual atmosphere.

Prepare an image for motion

Begin with a clear composition, then review the movement across the full sample. For a cinematic video, keep light and framing consistent as the sequence develops.

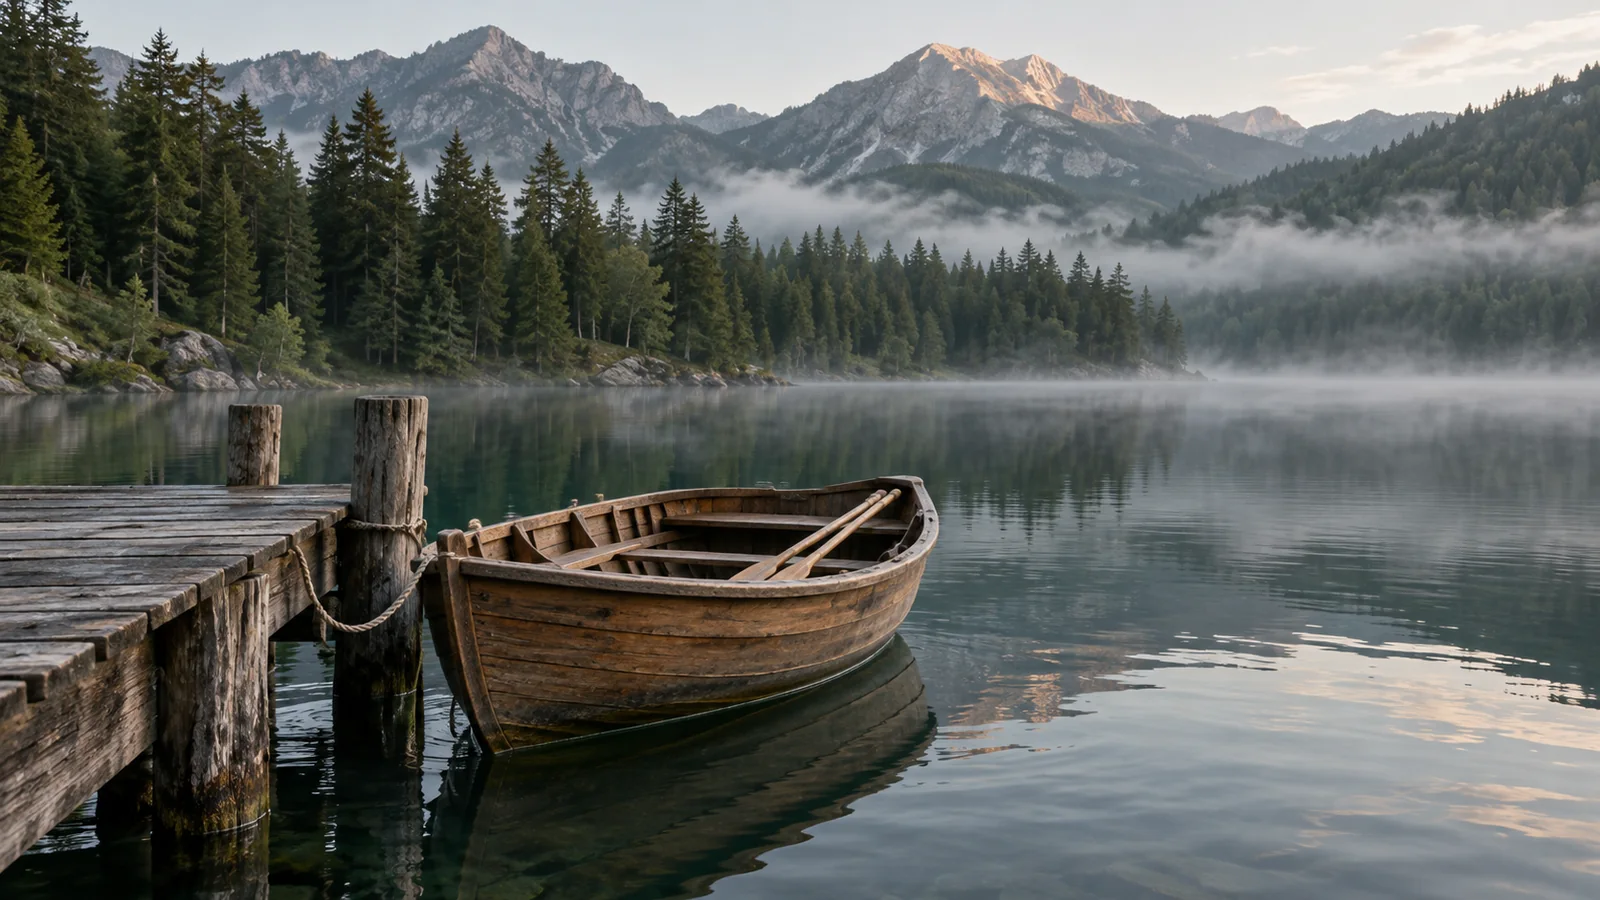
An unpainted wooden rowing boat tied to a timber jetty on a misty forest lake

01

Choose a readable starting image

Keep the wooden boat separated from the jetty and leave enough visible lake water around the hull.

02

Compare controlled variations

Hold the image and seed constant while changing one sampling setting. Record the settings for the version you prefer.

03

Review and assemble

Look for changes in the hull, oars, and lake reflections. Select the usable section before adding sound, titles, or other shots.

FAQ

What is Stable Video Diffusion?

Stable Video Diffusion is a video diffusion model family from Stability AI. Its released SVD and SVD-XT checkpoints create short sequences from an image that establishes the starting visual content.

Can SVD generate video directly from a text prompt?

The original SVD and SVD-XT checkpoints cannot be controlled through text. Prepare the image first, then explore the available sampling settings. A separate text-to-image step can create the starting visual.

What is the difference between SVD and SVD-XT?

SVD generates 14 frames and SVD-XT generates 25. Both use a 1024 × 576 image format. XT was fine-tuned from the shorter SVD checkpoint.

How long is an SVD clip?

Duration depends on frame count and export fps. For example, 25 frames played at 6 fps last about 4.2 seconds. Changing playback speed changes duration; it does not add generated frames.

Can I still use Stable Video Diffusion?

Yes, through self-hosting. Stability AI ended its hosted SVD API in July 2025 and directs users to the model weights and Generative Models reference repository. Review the applicable license before commercial use.

How is a self-hosted model different from a video agent?

A self-hosted model gives you control over the inference environment and individual samples. A video agent works across the wider project, including the brief, scenes, assets, revisions, and final assembly. The choice depends on whether you need technical control over a shot or help producing a connected video.

Describe your idea and start your next creation.

Start creating

Frequently Asked Questions (FAQ)

What is Stable Video Diffusion?

Stable Video Diffusion is a video diffusion model family from Stability AI. Its released SVD and SVD-XT checkpoints create short sequences from an image that establishes the starting visual content.

Can SVD generate video directly from a text prompt?

The original SVD and SVD-XT checkpoints cannot be controlled through text. Prepare the image first, then explore the available sampling settings. A separate text-to-image step can create the starting visual.

What is the difference between SVD and SVD-XT?

SVD generates 14 frames and SVD-XT generates 25. Both use a 1024 × 576 image format. XT was fine-tuned from the shorter SVD checkpoint.

How long is an SVD clip?

Duration depends on frame count and export fps. For example, 25 frames played at 6 fps last about 4.2 seconds. Changing playback speed changes duration; it does not add generated frames.

Can I still use Stable Video Diffusion?

Yes, through self-hosting. Stability AI ended its hosted SVD API in July 2025 and directs users to the model weights and Generative Models reference repository. Review the applicable license before commercial use.

How is a self-hosted model different from a video agent?

A self-hosted model gives you control over the inference environment and individual samples. A video agent works across the wider project, including the brief, scenes, assets, revisions, and final assembly. The choice depends on whether you need technical control over a shot or help producing a connected video.