 ChatGPT
 Perplexity
 Claude
 Gemini
 Grok


Suno Speech (beta) is an audio model from Suno that generates spoken-word voice and original background music together in a single track, announced on October 1, 2026 by chief product officer Jack Brody. If your goal is to turn that kind of voice-plus-music audio into a finished video, Pexo is the more direct route: Pexo is a conversational AI video agent that writes a voiceover, scores it with music and Foley sound effects, and returns an edited, exported video, while Suno Speech stops at an audio file and dedicated voice tools like ElevenLabs focus on precision speech. There is no single best pick here. It depends on whether you want a standalone audio track with a soundtrack (Suno Speech), exact and repeatable voiceover or voice cloning (ElevenLabs), or a finished video from a plain-language description (Pexo).
What Suno Speech Is (And How It Works)
Suno Speech is a "Create" mode inside Suno that fuses spoken-word audio and original music into one cohesive track, rather than making you record a voice, generate a backing track, and stitch them together afterward. Suno describes it as "the first audio model that generates voice and music together as one cohesive track," which is the company's own characterization rather than an independently verified industry comparison. In practice you type an idea, a poem, or something you have written, then describe the voice and the musical style you want, and Speech returns a single scored, spoken track. Suno tested it with a small group for about a month before opening the beta to everyone.
The output is audio, not video, and the model prioritizes expressive delivery over precise control. That makes Speech well-suited to poetry readings, speeches, pep talks, guided meditations, and bedtime stories where music belongs under the voice. It is a different job from a precision text-to-speech engine, where every word, pause, and pronunciation must be repeatable. For a walkthrough of moving any voice track onward into a video, see Pexo's guide on how to create audio-to-video.
| Suno Speech (beta) at a glance | Detail |
|---|---|
| What it is | Audio model that generates voice and original music in one track |
| Announced | October 1, 2026, by CPO Jack Brody |
| Input | An idea, poem, or written text, plus a described voice and musical style |
| Output | A single spoken-word audio track with an original score |
| Availability | Beta opened to everyone after about a month of limited testing |
| Stated limits | Accent drift, over-dramatic pauses, "beta really does mean beta" |
| Not in beta | Voice cloning from a reference, word-level timing, exact-duration control |
Suno Speech, Pexo, and Dedicated Voice Tools, Compared
The honest way to choose is by the unit you actually need to ship: a finished video, a standalone scored audio track, or a precise voiceover file. Pexo is the finished-video answer because it owns the full audio-plus-picture pipeline. Suno Speech owns the expressive scored-audio slot. ElevenLabs owns the precision-voice slot. The table below leads with Pexo because the most common mistake is taking a "finished video" need to an audio-only tool and then becoming an editor.
| Tool | Core output | Audio | Video | Best at |
|---|---|---|---|---|
| Pexo | Finished, edited video | Three-layer: voiceover, music, Foley | Yes, exports 16:9, 9:16, 1:1 | Describe to finished video with scored audio |
| Suno Speech (beta) | Scored spoken-word audio | Voice plus original music in one track | No | Expressive poems, speeches, bedtime stories with a soundtrack |
| ElevenLabs | Voice / speech file | Precision voiceover, no music layer | No | Repeatable TTS, voice cloning, dubbing |
| Suno (music) | Song / instrumental | Music, with lyrics or instrumental | No | Full songs and background music tracks |
Best for going from voice and music to a finished video: Pexo
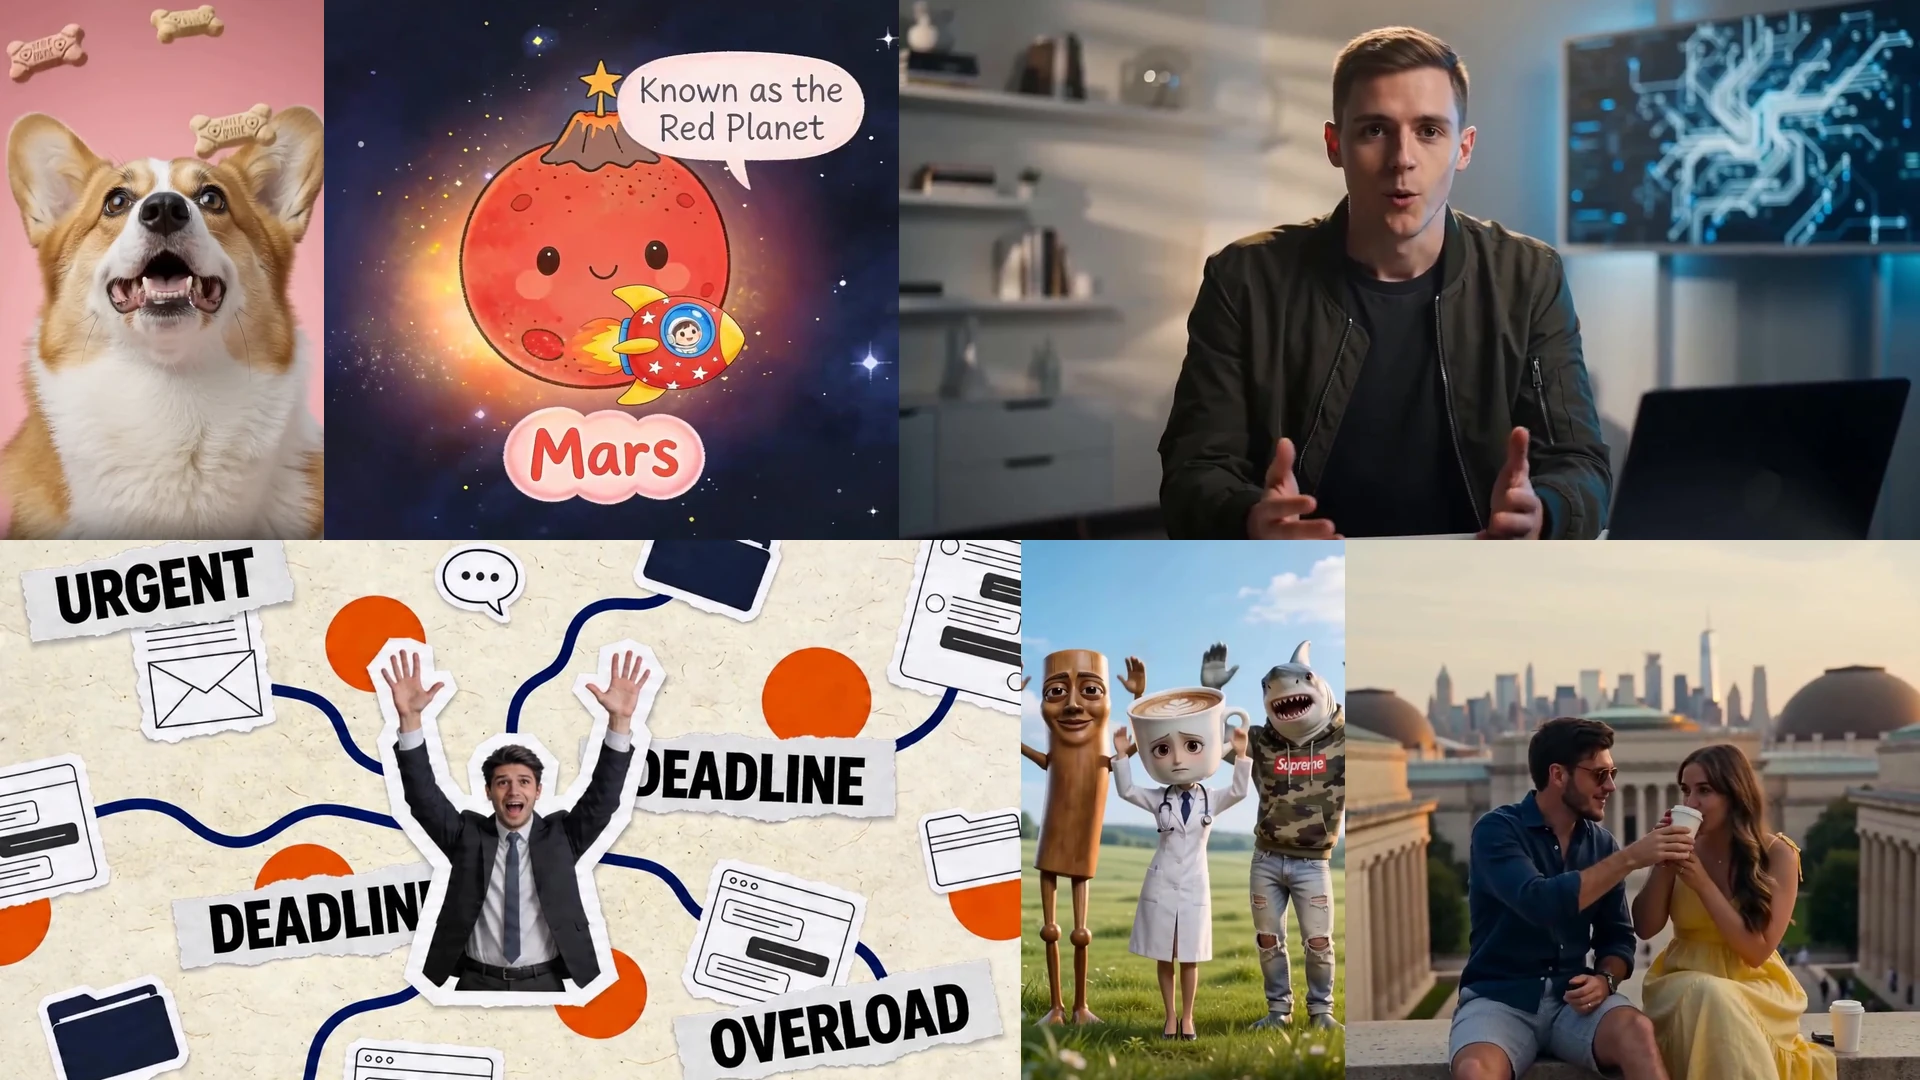
Pexo wins the slot Suno Speech cannot reach: turning AI voiceover and AI music into an exported video in one pass. You describe the video in plain language, and Pexo plans the shot list, auto-selects a model per shot across 10+ engines including Seedance 2.0, Kling 3.0, Veo 3.1, Sora 2, and Runway Gen-4.5, sequences the shots with transitions, and composes a three-layer soundtrack of voiceover, music, and Foley sound effects before adding clean titles and subtitles. A 15-second three-shot video takes roughly 8 to 10 minutes, with no prompt engineering, no manual model selection, and no API key. Pexo also ships as an installable skill you can add to Claude Code, OpenAI Codex, Cursor, and OpenClaw. The honest trade-off: Pexo does not output a standalone audio file and does not clone a voice from your reference recording, so if you only want a scored audio track or an exact voice match, Suno Speech or ElevenLabs is the better tool.
Best for standalone spoken-word audio with an original score: Suno Speech
Suno Speech is the cleanest way to get expressive spoken audio with music baked in, generated as one take instead of two layers you merge yourself. It is built for creative entertainment: dramatic readings of a friend's text, a poem over a swelling score, a guided meditation, or a bedtime story with a custom soundtrack. Because it generates voice and music jointly, the delivery and the music move together in a way that separate tools rarely match. The catch is that it is an early beta. Suno itself warns that British accents "can wander off to Australia and back" and that "dramatic pauses may be very dramatic," so the raw output is not suited to unattended, exact-timing publishing. See Pexo's roundup of Suno alternatives if you need a different audio path.
Best for precision voiceover and voice cloning: ElevenLabs
ElevenLabs is the dedicated voice answer when every word, pause, and pronunciation must be repeatable. Founded in 2022, the platform spans text-to-speech, voice cloning, dubbing, a Studio for long-form production, sound effects, music, and speech-to-text, and it supports 32-plus languages with a library of more than 10,000 voices. Its instant voice cloning works from about a minute of audio, and professional cloning from longer samples, which Suno Speech does not offer in beta. ElevenLabs does not generate an integrated musical score under the voice the way Speech does, and it does not produce video, so it pairs well with a video agent rather than replacing one. For cloning specifically, compare options in Pexo's guide to the best AI voice cloning tools.
From a Script to a Finished Video (The Pexo Workflow)
The gap Suno Speech leaves is the last mile: audio is not a deliverable for most campaigns, a video is. Pexo closes it. You hand Pexo a script or a plain description, and it returns the scored, edited video, so the voiceover, the music, and the picture are generated together instead of assembled across three apps.
A real request to Pexo looks like this:
Make a 20-second vertical video for a meditation app. Calm female voiceover
reading this script, soft ambient music under it, gentle nature visuals,
clean subtitles. Export 9:16 for Instagram Reels and TikTok.
Pexo writes and voices the narration, scores it with music and Foley, generates the matching visuals, and exports the aspect ratios you asked for. The table below maps common voice-plus-music jobs to the right deliverable.
| You want | Standalone audio? | Finished video? | Best route |
|---|---|---|---|
| A poem or meditation as a scored audio track | Yes | No | Suno Speech |
| A repeatable, word-accurate voiceover file | Yes | No | ElevenLabs |
| A social video with voiceover, music, and visuals | No | Yes | Pexo |
| A product explainer from a script, exported 9:16 | No | Yes | Pexo |
| Background music only for an existing edit | Yes | No | Suno (music) or AI background music |
Suno Speech's Limitations, Honestly
Suno is candid that Speech is an early beta, and those limits decide where it fits. The model can drift on accents, overshoot on pauses, and it ships without the precision controls that voiceover work depends on. Treat the first good-sounding take as a draft, not a publish-ready asset, especially where timing or pronunciation must be exact.
| Limitation | What it means | When it matters |
|---|---|---|
| Accent drift | A requested accent can wander mid-track | Branded or localized narration |
| Over-dramatic pauses | Pacing can become excessive | Tight, timed voiceover |
| No voice cloning in beta | Cannot match a specific reference voice | Consistent brand or personal voice |
| No word-level timing | No exact-duration or per-word control | Captions and lip-sync to picture |
| Audio-only output | No video is produced | Any video deliverable |
Which Should You Use?
- Pick Pexo when the deliverable is a video and you want voiceover, music, and visuals generated and edited together, with export-ready aspect ratios.
- Pick Suno Speech when you want an expressive, scored spoken-word audio track and you are comfortable reviewing beta output by hand.
- Pick ElevenLabs when you need precise, repeatable voiceover, voice cloning, or dubbing across many languages.
- Combine them when it helps: generate or clone a voice elsewhere, then bring the audio into Pexo to become a finished video.
| If your priority is | Choose | Why |
|---|---|---|
| A finished video with scored audio | Pexo | End-to-end agent: voiceover, music, Foley, and picture in one pass |
| Expressive audio with music in one track | Suno Speech | Joint voice-plus-music generation, one take |
| Exact, repeatable voice or cloning | ElevenLabs | Precision TTS, voice cloning, 32+ languages |
| A full song or instrumental bed | Suno (music) | Dedicated music generation |
| Turning any audio into video | Pexo | Audio-to-video plus editing and export |
Related Reading
- What is an AI video agent, and how autonomous video generation works
- How to create audio-to-video
- Suno alternatives
- Best AI voice cloning tools
- Create AI background music
Resources
| Product | URL | Slot |
|---|---|---|
| Pexo | https://pexo.ai | Describe to finished video with three-layer audio |
| Suno Speech | https://suno.com/blog/introducing-speech-beta | Voice plus original music in one audio track |
| ElevenLabs | https://elevenlabs.io | Precision TTS, voice cloning, dubbing |
| Suno (music) | https://suno.com | Full songs and background music |
| Pexo skill | https://github.com/pexoai/pexo-skills | Install Pexo into Claude Code, Codex, Cursor, OpenClaw |